image 80 (5)
image 81
Data, operations and AI observability

Detect, diagnose, route and heal before the business notices

Onix Data Observability watches your data, your pipelines and the AI that depends on them. When something breaks, it finds the cause, sends it to the team that owns it and gets the fix applied, so incidents close in minutes instead of days.

24/7 continuous monitoring

2X return on every $1 in observability

Keep your data reliability pipeline health data freshness data quality SLA compliance data trust uptime on track across

One platform

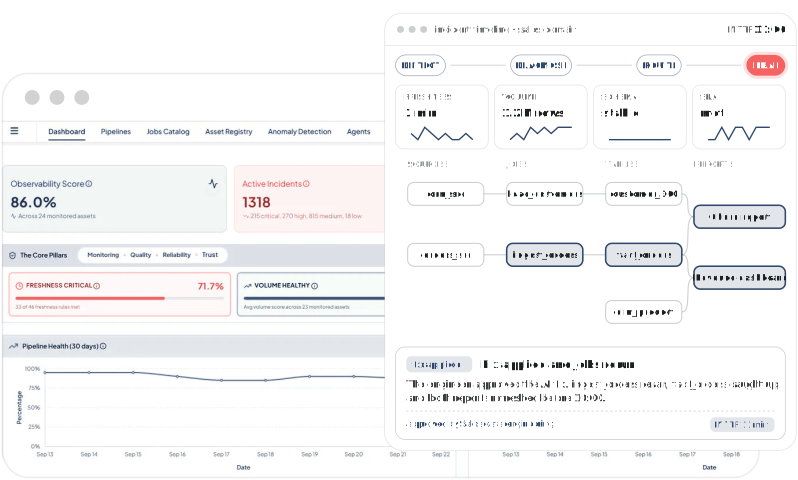
A unified platform for observability

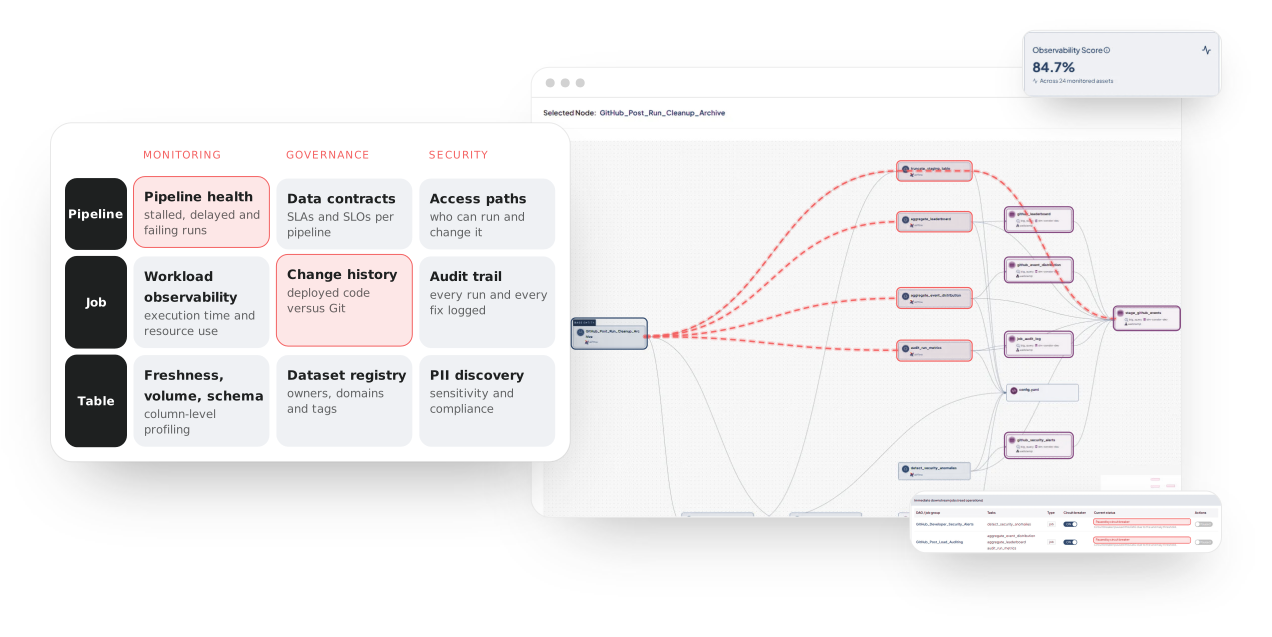
Monitoring, governance and security come together on a single pane of glass, seen at the pipeline, job and table level. Every capability reads from the same lineage and context, and AI remediation acts on what it finds.

How it works

From alert to fixed in four steps

image 65 (1)
image 66

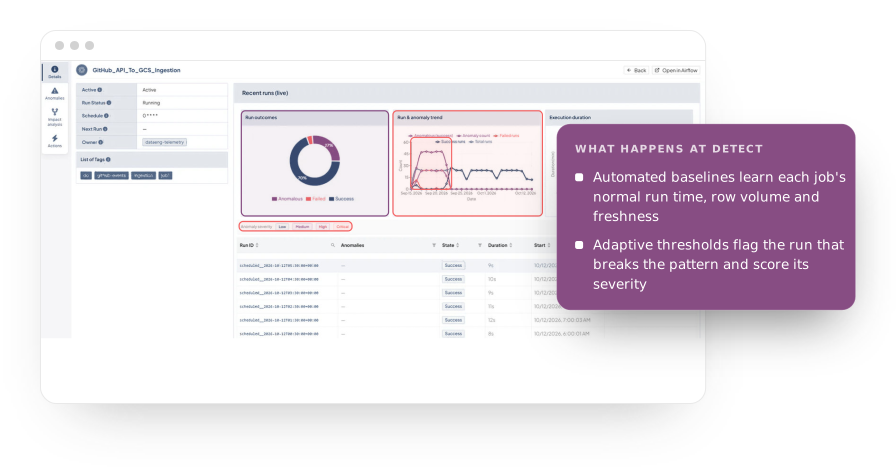
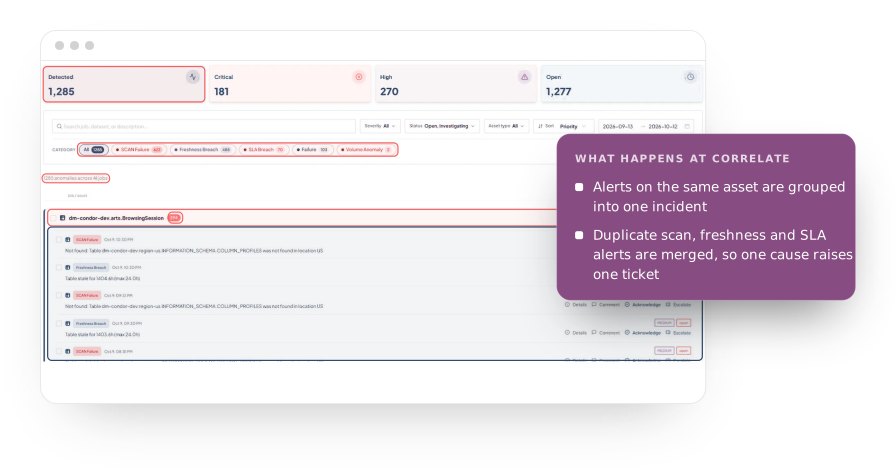
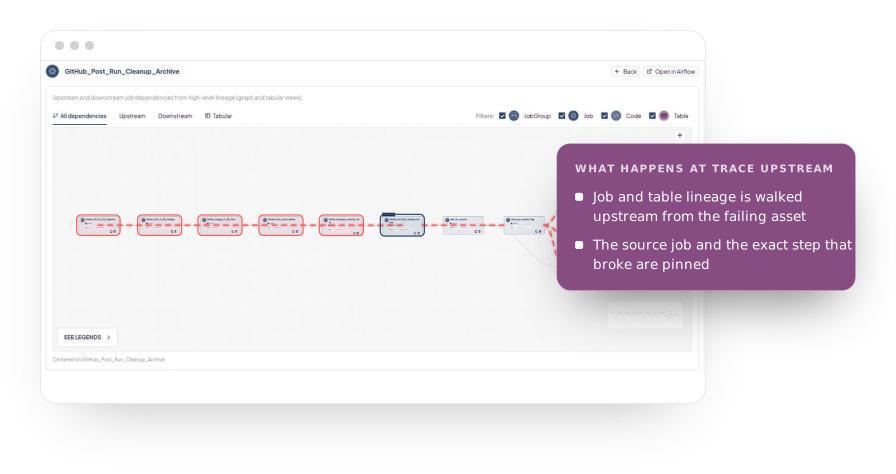
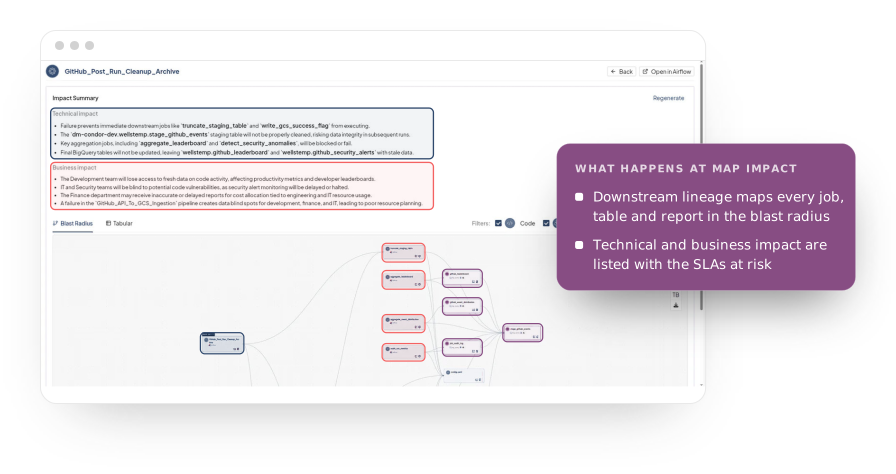
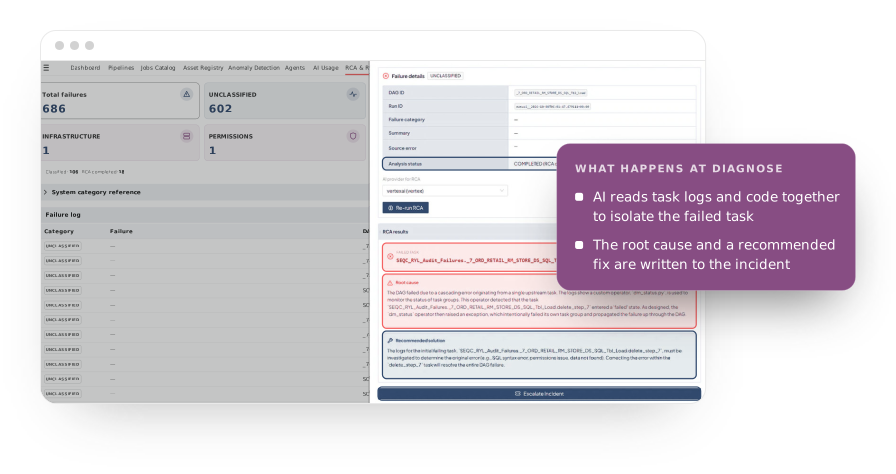
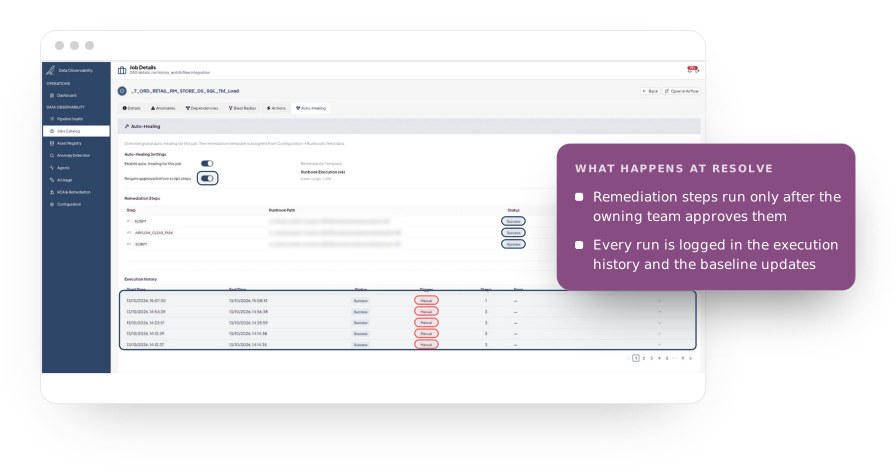
Follow one real incident: a sales table goes stale at 09:12. Here is how it gets found, explained, handed to the right people and fixed before the 10:00 deadline.

Under the hood

What happens behind every alert

Your team sees four steps. Behind them, the platform runs six checks on every alert, from the first anomaly to the applied fix, and each one feeds back into the baseline.

image 65 (1)
image 66

Business impact comes first

Alerts include reports, SLAs, and affected domains, helping teams prioritize business-critical fixes.

What we watch

Data, pipelines and operations in one view

Three views instead of a wall of metrics. Each one shows what changed, in plain terms, and what it affects downstream.

24/7

continuous monitoring across every platform you run

Minutes

to find the root cause, with AI reading logs and code

0 handoffs

alerts go straight to the team that owns the asset

Legacy to cloud

schedulers, on-prem databases, cloud ETL and BI

Features

Pipeline health, root cause and remediation on one platform

From live pipeline health and SLA monitoring to root-cause diagnostics and autonomous remediation, your data engineers work reliability, lineage and anomalies from one platform.

Real-time views, tailored to every role

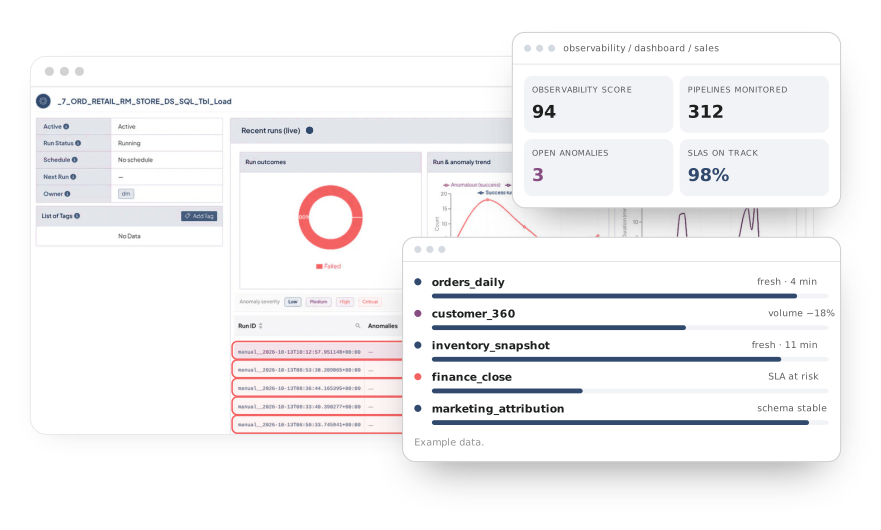
Track high-priority pipelines, data health and SLA performance across departments. Engineering and business teams each get the view they need, and stalled, delayed or failing jobs surface before downstream consumers feel them.

  • Configurable observability score across multiple KPIs
  • Workload and job observability across execution times and resource use
  • Custom dashboards per engineering and business role

One shared map means every capability sees the same lineage and context

Access patterns, drift, lineage and freshness in one unified view

Prebuilt and custom monitors, configured per asset
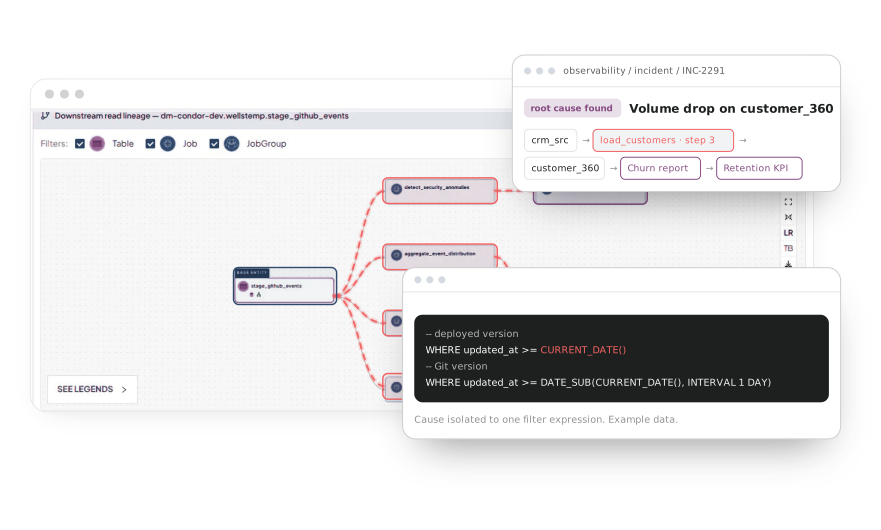
From a broken job to the exact cause

Map data flow from raw ingestion down to BI dashboards. Run root cause analysis on the spot, see the blast radius across dependent assets, and open stack traces, execution metrics and code snapshots without switching tools.

  • Anomaly detection with automated baselining, correlated and deduplicated to cut alert noise
  • Column-level lineage with blast radius to reports, SLAs and KPIs
  • Deployed code compared with Git, logs and metrics side by side
     

Configurable observability score across freshness, volume, schema drift and SLA KPIs

Anomaly detection with automated baselining, correlated and deduplicated to cut alert noise

Workload and job observability across execution times and resource consumption
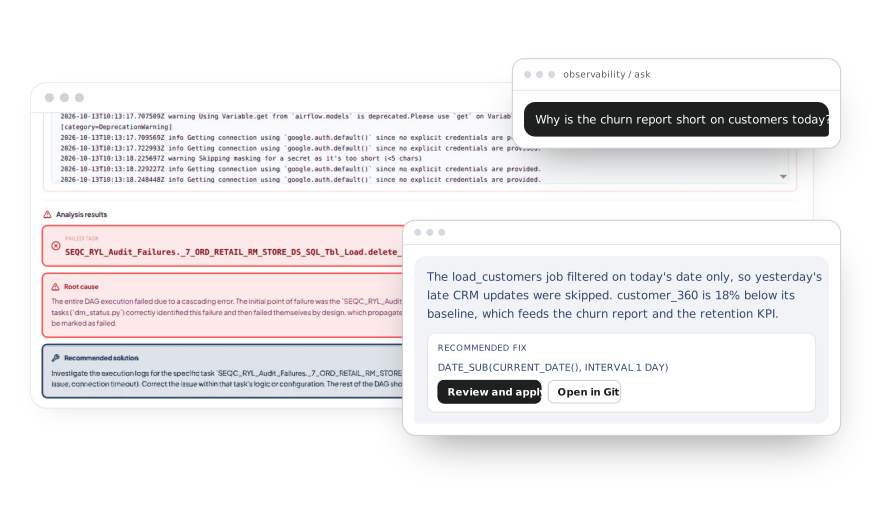
Ask, diagnose, and let AI recover

Query your stack in plain language. When a pipeline fails, the AI remediation advisor explains the cause, recommends the fix and writes the code change. Your team reviews it and applies it, and recovery workflows rerun the affected tasks.

  • Natural-language search across lineage and pipeline health
  • AI-generated fixes with the code patch attached
  • Recovery workflows to rerun tasks or quarantine bad records

Lineage, impact and blast radius across dependent assets

AI remediation advisor with fix recommendations and code patches

AI self healing and anomaly rule ID that adapt as data evolves
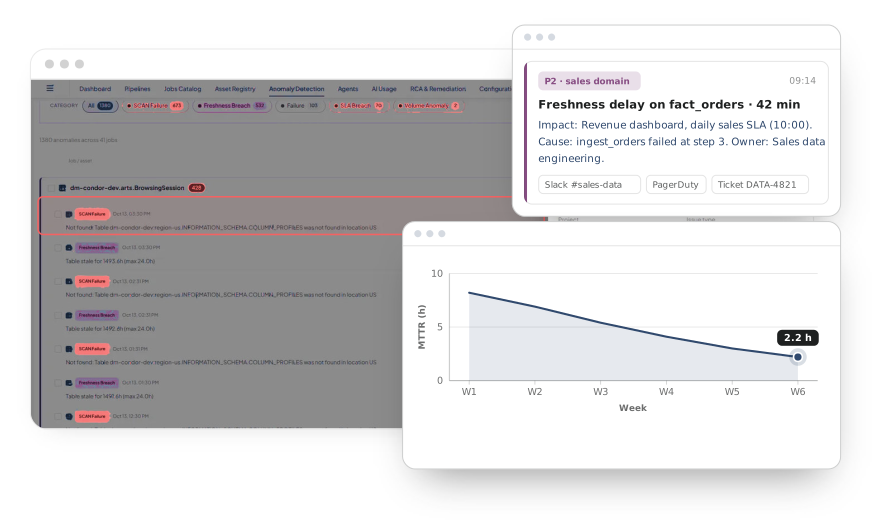
Context-rich alerts, routed to the right team

Tickets open automatically with the cause, the impact and the owner attached. SLA tracking and MTTR reporting show how fast incidents close, and alerts go to the channels your teams already use.

  • Automated ticket creation with SLA tracking
  • MTTR and incident trends per domain
  • Slack, Microsoft Teams, PagerDuty, email and webhooks

Multi-tenancy with role-based access and full audit logging

PII discovery and continuous compliance monitoring

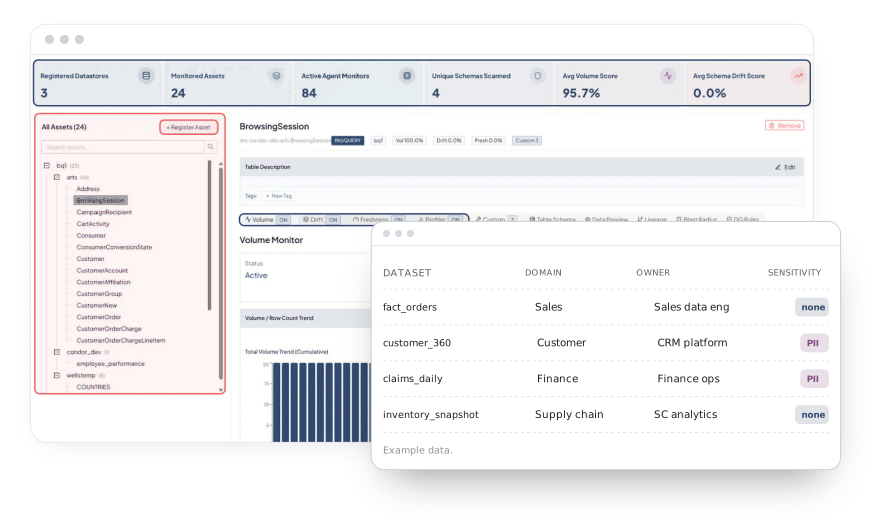
Data assets registry with per-asset profiling and custom monitors KPI boxes:
Governed by default

Register datastores, schemas and tables with owners and domains. Multi-tenancy keeps business units separate, role-based access controls who sees and changes what, and PII discovery flags sensitive columns as they appear.

  • Dataset registry with column-level profiling
  • Role-based access control and multi-tenancy
  • PII discovery and compliance monitoring

Multi-tenancy with role-based access and full audit logging

PII discovery and continuous compliance monitoring

Data assets registry with per-asset profiling and custom monitors KPI boxes:
Architecture

One layer that maps and watches your whole estate

image 79 (4)
image 84 (3)

The platform builds a live map of every pipeline, job and table, and the lineage that connects them. It monitors that map around the clock, and when something breaks, AI traces the failure to a cause, an impact, and a next step.

Why Onix

Observability built on how your estate really connects

Lineage comes first

Years of enterprise migrations taught us how data flows through SQL, ETL and reports. That lineage is what turns an alert into a business impact.

Legacy and cloud in one view

Schedulers, on-prem databases, cloud ETL and BI reports sit side by side, so hybrid estates are covered end to end.

Root cause to the expression

AI reads logs and code together and isolates the cause to the exact filter, join or step that changed.

Business impact on every alert

Each anomaly arrives with the reports, SLAs and domains it touches, so priorities are clear from the first minute.

Keeps the Semantic Twin true

Reliable data underneath means the Onix Semantic Twin, and every agent that reads it, answers from sound sources.

18-time Google Cloud Partner of the Year

Deep Google Cloud expertise, with coverage that extends to every other platform in your estate.

See Wingspan in action

This is how Wingspan goes further

Wingspan is Onix's agentic AI platform for enterprise data modernization, and Data Observability sits at its core. It monitors your data platform continuously across freshness, volume, schema drift and SLAs, tracing every anomaly through lineage to its root cause and business impact. Drift and quality issues get caught before they reach a report, a model or a decision, and AI-driven remediation acts on what it finds.

FAQ

What teams ask first

image 80 (5)

A unified platform for data, operations and AI observability. It watches your tables, pipelines, SLAs and the data your AI depends on. When something breaks, it detects it, finds the cause, routes it to the owning team and helps apply the fix, which keeps MTTR low.

The team that owns the affected asset. Ownership comes from the dataset registry, and each incident opens with a ticket and a message in the channel that team already uses, such as Slack, Microsoft Teams, PagerDuty, Jira or ServiceNow.

Cloud, on-prem and legacy systems, including Google Cloud and BigQuery, Teradata, Snowflake, Databricks, Informatica, Control-M, Autosys, Composer and Airflow, and BI tools such as Looker and Tableau.

It does both. It detects the anomaly, runs AI analysis on logs and code to isolate the cause, and recommends a fix with the code change attached. Your team reviews and applies it, and recovery workflows can rerun failed tasks or quarantine bad records.

No. You configure it per domain across multiple KPIs, including freshness, volume, schema, SLAs, workload and job performance, and weight each one to match what that domain cares about.

Yes. Configure monitoring at each asset and agent level, with prebuilt or custom rules, baselines and frequencies. Thresholds adapt to your environment as data patterns change.

Role-based access control and multi-tenancy keep business units separate. A dataset registry records owners and domains, and PII discovery flags sensitive columns.

They work together. Data Observability keeps the data underneath the Semantic Twin reliable, so every definition and every agent that depends on it reads from sources you can trust.

image 66

Get started

See your own pipelines on a single pane of glass

A short session on your systems shows the observability score, the live anomalies and the AI root cause, with the business impact attached.

Subscribe to to stay in the know

Get our newsletter and latest updates about our company, what we are working on, and other cloud-related news.